Canarypwn’s Blog [index]
Canarypwn’s Blog [index]
This is the blog of canarypwn. I am a Ph.D. student at North Carolina State University. Here I write about various topics including programming, technology, and personal experiences. Stay tuned for updates!
Articles
1. A PhD Survival Guide for the LLM Era [phd-survival-guide]
1. A PhD Survival Guide for the LLM Era [phd-survival-guide]
2. LLMs Know a Little About Where Bugs Are, but That Doesn't Make Fuzzing Faster [llm-guided-fuzzing]
2. LLMs Know a Little About Where Bugs Are, but That Doesn't Make Fuzzing Faster [llm-guided-fuzzing]
Technical report, October 2026. Mostly negative results from using a language model’s hidden states to decide where a coverage-guided fuzzer should spend its time.
Reading transcripts of LLM agents hunting for bugs, I was surprised how often the agent says where the bug is before it has written a single test. It reads a function, points out that a length is never checked against the buffer it indexes, and only then writes the test that proves it. If a model can see that in the code, a fuzzer should be able to use it. Coverage-guided fuzzers such as AFL and libFuzzer treat all new coverage the same, so even a cheap score saying “this function looks buggy” could tell them where to spend their mutations.
So I built llmfuzz, a fuzzer that reads a language model’s hidden states for every function of a C/C++ program, turns them into a “looks buggy” score, and spends more of its budget where the score is high. That did not make fuzzing faster than weighting functions by their size, and most of the later experiments were attempts to get a stronger signal out of the model. I tried bigger models, call-graph and AST context, and letting the model reason or write a doc comment before it answers. Finally I tested it on bugs fixed after the model was released, which it cannot have memorized.
The model does know a little about where bugs are, and on the recent bugs this is not memorization. But the effect is small. A function scores somewhat higher while it contains the bug than after the fix, yet different functions differ from each other by much more than that, and the plain rule “longer functions are more suspicious” ranked the bugs better. Even a perfect predictor would have made the fuzzer at most about twice as fast on the bugs I tried, because the fuzzer reached the buggy functions early and spent most of its time looking for the input that triggers the bug.
Summary
- A probe on Qwen3.6-27B’s hidden states separates vulnerable from non-vulnerable functions of similar length with an AUC of 0.575. The same probe on Qwen3-4B gets 0.565, and the difference is within noise. On 13 known bugs in Google’s fuzzer-test-suite the 27B puts the buggy function at a median percentile of 41 (the 4B at 27), where ranking by function size alone gives 15.
- Weighting the fuzzer by the 27B’s scores helped on Linux and hurt on macOS. On two Linux machines the time to the first crash was 0.62× and 0.88× that of unweighted fuzzing (geometric mean of the per-target medians), but most of that came from hitting out-of-memory errors in libcxxabi sooner. If out-of-memory errors and timeouts are not counted as finds, it was 1.00× and 1.37×. Weights from function size alone gave 0.52×. On macOS the 27B was slower on all three targets (1.87×). The 4B’s earlier speedup on macOS (0.30×) did not repeat on a second Mac (1.01×).
- A perfect ranking helps at most about 2×. Putting the true buggy function first made woff2 crash 1.9× sooner and lcms no sooner, and random scores on the other functions erased even that.
- Context did not help. On four models from 4B to 27B parameters, none of ten kinds of context (callers, callees, call stacks, AST-selected definitions, argument slices and more) did better than the same amount of random code from the same file.
- Reasoning first helps a little. When Qwen3.6-27B first writes a doc comment for the function, it ranks the bugs higher (median percentile 35 → 20), and a comment written for another function makes it worse (50). No form of reasoning beat ranking by size, and the 27B’s reasoning openly recognizes famous bugs.
- On 148 single-function fixes committed after the model’s release, Qwen3.6-27B gives the buggy version a higher score than the fixed version 76% of the time, which neither code size nor the number of if-checks explains. Its own Yes/No answers are right for both versions in only 11% of the pairs.
How llmfuzz works
Scoring code with the J-lens
llmfuzz cuts a program into chunks, one per function, and splits functions longer than 150 lines into 150-line chunks. It runs each chunk through the model once, with a review question at the end:
// File: cmsintrp.c
... code of the chunk ...
/* Code review. Q: Is there a bug in the function above? A:
Instead of letting the model answer, llmfuzz reads the Jacobian lens (J-lens) at the last position. The J-lens comes from Anthropic’s Verbalizable Representations Form a Global Workspace in Language Models (arXiv:2607.15495). It maps a layer’s residual stream into the final layer’s coordinates with the average Jacobian between the two, \(J_\ell = \mathbb{E}[\partial h_{\text{final}} / \partial h_\ell]\), and decodes the result with the model’s own unembedding: \(\mathrm{lens}_\ell(h_\ell) = \mathrm{lm\_head}(\mathrm{norm}(J_\ell h_\ell))\). Roughly, it shows what each layer is getting ready to say. I used the lenses that Neuronpedia has fit for Qwen3 and Qwen3.6.
I take two scores from the lens. The first needs no training: \(\log P(\text{yes}) - \log P(\text{no})\), averaged over the last quarter of the layers. I call it the zero-shot score. The second is a logistic-regression probe over the lens probabilities of a few hundred tokens (concept words such as “overflow”, “bounds” and “unchecked”, plus tokens the lens often produces at the question) in the last third of the layers, trained on 3,000 functions from PrimeVul, a dataset of C/C++ functions taken from vulnerability-fixing commits. Each vulnerable training function is paired with a non-vulnerable function from the same project whose length is within 15%, so the probe cannot get away with learning that long functions are vulnerable. The probe and fuzzing experiments below use Qwen3.6-27B (208 tokens at 22 layers). I first ran them with Qwen3-4B (179 tokens at 12 layers) and give its numbers for comparison.
How the scores change fuzzing
The fuzzer is a libFuzzer-compatible SanitizerCoverage runtime of about 1,100 lines of C. llmfuzz standardizes the scores within each program and maps them to per-edge weights \(w = \mathrm{clip}(e^{z}, 0.5, 8)\). The weights are used in two places. A seed’s energy, which decides how often it is picked for mutation, is a weighted sum over the coverage features it was first to discover, \(\sum w^{\gamma} / \sqrt{1 + \text{hits}/256}\), so seeds that reach suspicious code are mutated more. Comparison-operand feedback (libFuzzer’s “value profile”) is turned on only in the top 10% of the code. One pick in ten ignores the weights, so a wrong ranking cannot shut the rest of the program out. Without a weight file neither mechanism is active, so the baseline is the same engine. That baseline holds its own against libFuzzer on the same harnesses, seeds and budget: it is faster on lcms and pcre2, slower on libcxxabi and about even on the rest.
How strong is the signal?
On PrimeVul’s test split the probe does better than chance, but not by much, and no better than counting lines. The 27B does no better than the 4B.
| Test set | 27B probe | 27B zero-shot | 4B probe | 4B zero-shot | Line count |
|---|---|---|---|---|---|
| Length-matched pairs | 0.575 | 0.551 | 0.565 | 0.552 | 0.507 |
| Natural distribution | 0.603 | 0.675 | 0.617 | 0.679 | 0.800 |
On the length-matched pairs, where length alone is at chance, the probe still scores above 0.5, so the hidden states carry some information beyond length. The larger model does not carry more of it. Every difference between the 27B and the 4B lies inside its 95% bootstrap interval, which is about ±0.05 wide. The cross-validation chose the strongest regularization in its grid, and making it up to 100 times stronger kept the 27B’s test AUCs between 0.575 and 0.620. On the natural distribution that information is small next to length itself. Longer functions are more likely to contain vulnerabilities, and the zero-shot score does better there mainly because it correlates with length.
The fuzzing benchmark is seven targets from Google’s fuzzer-test-suite (FTS): libcxxabi, pcre2, lcms, woff2, OpenSSL 1.0.1f with Heartbleed, re2 and libxml2. They contain 13 known bug functions, and each target has 80 to 4,354 chunks.
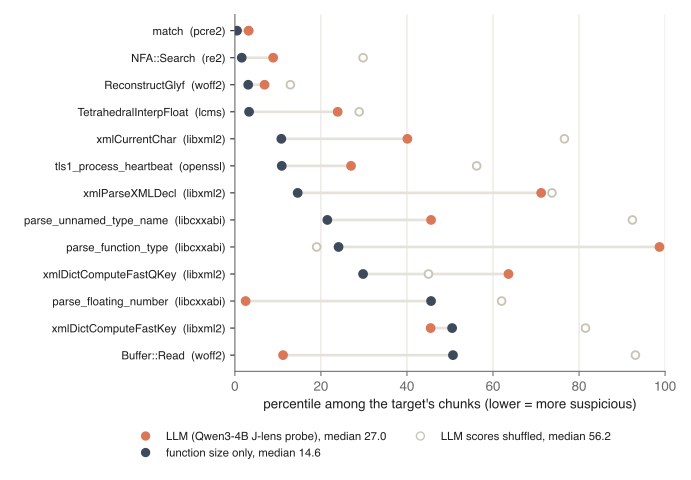
The 27B puts 3 of the 13 bug functions in the top 10% of their target. Sometimes it is right where size is wrong: it ranks woff2′s Buffer::Read 4th of 449 chunks, while size puts it in the middle. It can also be far off: the two libxml2 hash functions land at the 94th and 98th percentile. Over all 13 bugs, ranking by size alone does better (median percentile 14.6 against 41.2), and so does the 4B (27.1). Bug by bug, the 27B ranks 5 bugs higher than the 4B and 8 lower. The 4B’s best hit, libcxxabi’s parse_floating_number at 2nd of 80 chunks, is at the 41st percentile under the 27B.
Fuzzing with LLM weights
Every configuration runs the same engine and binary; only the weight file changes. A trial is a single process with a 900-second budget. I measure the time to the first crash, counting timeouts and out-of-memory errors as crashes and trials that find nothing as 900 s. Each target gets 8 trials per configuration, and all configurations in a column of the table below ran in the same batch on the same machine.
| Weights | Linux | Linux, 2nd machine | macOS |
|---|---|---|---|
| LLM (27B) | 0.62× (3/5) | 0.88× (2/5) | 1.87× (0/3) |
| LLM (4B) | 1.06× (1/5) | – | 1.01× (1/3) |
| Size only | 0.52× (5/5) | – | 1.15× (1/3) |
| LLM (27B) + size | 0.98× (3/5) | – | 1.28× (1/3) |
| LLM (27B) shuffled | 1.60× (1/5) | – | 1.39× (1/3) |
| libFuzzer | 1.20× (2/5) | – | – |
On macOS the 27B was slower than unweighted fuzzing on all three targets. On libcxxabi the crash is in parse_floating_number. (The bug is a stack overflow that exists only on Apple arm64, where long double has 8 bytes but the demangler parses 16.) The 4B ranks that function 2nd of 80 chunks and found the bug in 1.0 s, against 2.7 s without weights (p = 0.009, Mann-Whitney U). The 27B ranks it at the 41st percentile and needed 9.8 s. On lcms, shuffling the 27B’s scores worked better than the scores themselves (5 of 8 trials found the bug, against 1 of 8; p = 0.026).
I first ran the macOS experiment with the 4B on an M5 Max, where it was faster on all three targets (0.30×; on libcxxabi 0.6 s against 4.7 s). On the M1 Ultra the 4B gave 1.01×, faster on libcxxabi and slower on woff2 (455 s against 168 s, p = 0.046), so the earlier speedup was not stable.
On Linux the 27B did better. On the main machine it was significantly faster than no weights on libcxxabi (47 s against 618 s, p = 0.027) and OpenSSL (1.6 s against 4.0 s, p = 0.036), and faster than its own shuffled scores on libcxxabi, OpenSSL and woff2. But all 8 of its libcxxabi finds were out-of-memory errors. libFuzzer finds a stack overflow there in 6 of 8 trials. llmfuzz found that stack overflow only once, in an unweighted trial. On pcre2 the 27B was slower (9.7 s against 2.6 s, p = 0.074) and ran at half the execution rate. Weights from function size alone were faster than no weights on all five targets (0.52×), though the difference was not significant on any single target.
The second Linux machine agreed on libcxxabi, OpenSSL and pcre2, but not on woff2, where the 27B went from slightly faster (223 s against 291 s) to slower (282 s against 99 s). With the 4B, the same two machines gave 1.00× and 1.58×.
Wrong weights can be expensive. One shuffled ranking pushed lcms’s mutations toward slow inputs and cut the execution rate to 131 executions per second, against 2,936 on average without weights, and that trial found nothing.
In the earlier runs with the 4B, two harder targets, libxml2 and re2, ran for 1,800 s. On libxml2 every weighted configuration (LLM, shuffled and size) did better than no weights, so there the weighting itself seems to help, and the LLM’s judgment has little to do with it. Final coverage of the code the LLM ranked highest was the same in every configuration; the weights only changed the order in which the fuzzer got there.
What a perfect ranking would buy
A ranking can fail because it is wrong, or because even a right one does not help. To tell the two apart, I replaced the LLM with an oracle that knows where the bug is and puts the crashing function at a chosen rank. In the simplest version, only the bug function is raised and all other functions get the same weight. In the noisy versions, the other functions get random scores, drawn again for every trial.
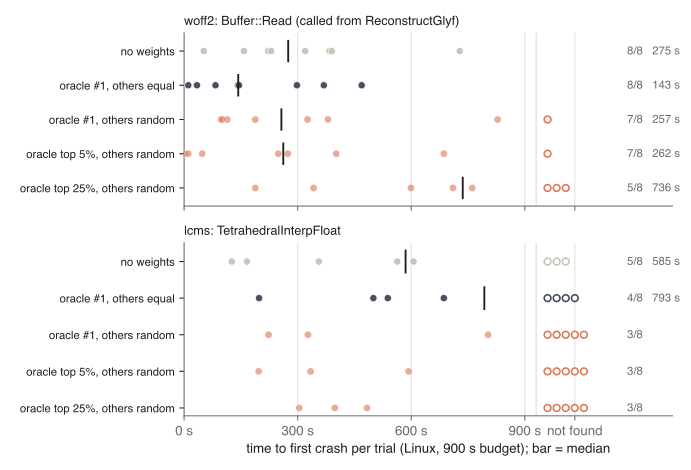
With the bug function first and the rest equal, woff2′s median went from 275 s to 143 s, 1.9× faster but not significant (p = 0.17). lcms got no faster. Its bug function sits in the inner loop of an interpolation routine, and ranking it first turned on comparison feedback there, which slowed execution by 26%.
Random scores on the other functions erase the gain. With the bug function still first but the rest random, woff2 was back at 257 s. With the bug function only somewhere in the top 25%, it was significantly slower than with no weights at all (736 s, p = 0.03).
Unweighted fuzzing reaches both bug functions early. The time goes into finding the particular combination of values that overflows the buffer, and putting more effort into inputs that reach the function does not produce it any sooner. Directed-fuzzing studies that use real bug locations found the same (LibAFLGo and AIJon, under related work). Even a perfect bug predictor, then, would have bought little on these bugs.
Adding context
Many vulnerabilities cannot be judged from one function. Whether an index is safe depends on what the callers pass in. So I put context in front of the function and repeated the ranking on four models: Qwen3-4B, and Qwen3-8B, Qwen3-14B and Qwen3.6-27B quantized to 4 bits. The call graph comes from the clang AST, starting at the fuzz harness.
The raw kinds of context, up to 3K tokens, are the first lines of every callee, the code around the call site in each caller, one call path from the harness down to the function, and the source text that precedes the function in its file. The selected kinds, up to 1.5K tokens per part, are the definitions of the macros, types, structures and globals the function uses, the statements in each caller that compute or check the call’s arguments (a backward slice by variable name), the callees’ signatures and comments, and a fixed-length window of surrounding code. As a control, the function gets random code from the same file, as long as the definitions.
| Context | Qwen3-4B | Qwen3-8B | Qwen3-14B | Qwen3.6-27B |
|---|---|---|---|---|
| Callees | 5–5 | 4–6 | 5–5 | 4–5 |
| Callers | 3–10 | 7–5 | – | – |
| Call stack | 4–5 | 9–2 | – | – |
| Call stack and callees | 7–6 | 8–5 | 8–4 | 7–5 |
| Preceding file text | 4–6 | 7–6 | 9–3 | 9–3 |
| Definitions | 5–6 | 5–5 | 7–3 | 5–4 |
| Caller argument slices | 6–4 | 6–4 | 6–3 | 5–4 |
| Definitions and slices | 7–4 | 8–5 | 10–2 | 8–4 |
| Callee signatures | 2–5 | 3–3 | 4–2 | 3–4 |
| Fixed window | 6–7 | 8–5 | 9–3 | 5–7 |
| Random code (control) | 6–4 | 7–4 | 9–0 | 6–3 |
Only two cells are significant. Both are for the 14B, and one of them is the random-code control. Given the function alone, the 14B ranked these bugs worse than chance, so almost any added code helps it, relevant or not. The best-looking number, a median percentile of 9.3 for the 27B with the preceding file text, became 30.2 with a fixed-length window instead. How much text comes before a function depends on where it sits in the file, and the 9.3 was probably an artifact of that.
There is an easy mistake to make here, and my first analysis made it. Context shifts the score of every chunk that receives it: same-length random code lowers the yes-no log-odds by 1.5 to 2.8. A bug function for which no context could be extracted keeps its unshifted score, and next to the shifted comparison chunks it looks more suspicious than it is. That first analysis reported a median percentile of 14.6 for the 4B with callees. Comparing only bug functions and comparison chunks that all received context gives 28.7.
Letting the model reason first
Everything so far reads a single forward pass, but the agents that impressed me reason before they answer. Maybe the knowledge only shows up once the model works through the code. I tried three ways of asking, in the chat format, on the same chunks.
- Answer directly. The question is “Does this function contain a bug (for example an out-of-bounds read or write, a use-after-free, an integer overflow or a logic error)? Answer with one word: Yes or No.” The lens is read where the answer starts.
- Think first. The model reasons, and then the lens is read at the same place. With a 512-token limit almost every chain of thought was cut off (91% for the 14B, all of them for the 27B), so I regenerated complete reasoning with vLLM, up to 8,192 tokens, and read the lens after it.
- Doc comment first. In a separate prompt, the model writes a short comment documenting the function: what it does, the preconditions on its arguments, and the invariants on buffer sizes and index ranges. It is told not to judge whether the code is correct. The comment goes above the code, and the model then answers directly. As a control, every function gets the comment the model wrote for another function of the same target.
| How the model is asked | Qwen3-14B | Qwen3.6-27B |
|---|---|---|
| Answer directly | 17.9% | 35.2% |
| Think first, ≤ 512 tokens | 27.8% (7–6) | 24.1% (5–8) |
| Think first, complete | 15.4% (7–6) | 18.3% (4–8)* |
| Doc comment first | 17.9% (7–5) | 20.1% (10–1) |
| Another function’s comment | – | 50.0% |
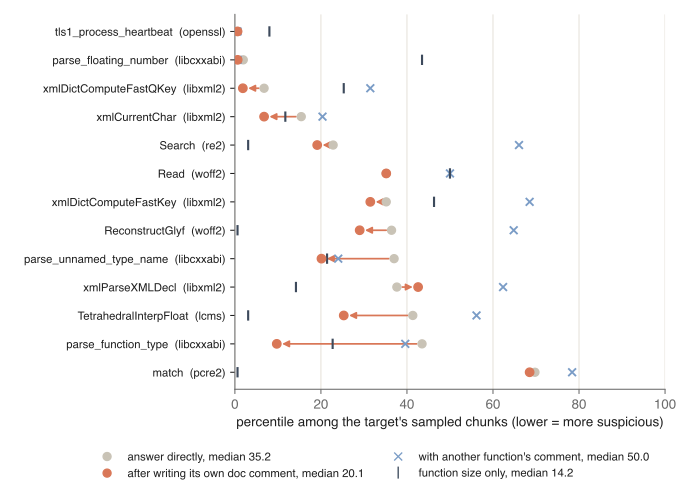
Writing a doc comment first helps the 27B. Its own comment moves the median from 35.2% to 20.1% (10 bugs up, 1 down, p = 0.01). Another function’s comment is worse than none (50.0%; own against other: 11–0, p = 0.001), so an extra comment by itself does not help. The comments often state the violated condition outright. For Heartbleed the model wrote payload (from message) must be <= s->s3->rrec.length - 3, which is exactly the missing check. The 14B gains nothing from its own comments.
Complete reasoning gives the 14B some information beyond size. Answering directly in this format, the 14B’s score mostly reflects function length: with size regressed out, the bugs sit at the 66th percentile, worse than chance. After complete reasoning they sit at the 33rd (12 up, 1 down, p = 0.003). Its own Yes/No answers also become more selective. It says Yes to 80% of the bug chunks and about half of the others, down from 100% and 86%. In its reasoning it names the actual cause for Heartbleed and for libxml2′s xmlDictComputeFastQKey (an index len - (plen + 2) that can go negative), and gives wrong reasons for most of the other bugs.
Reasoning that was cut off did not help either model, and complete reasoning did not help the 27B. None of these setups beat ranking by size: against size alone, the comment-first 27B is at 8–5, the 14B with complete reasoning at 5–8, and the 27B with complete reasoning at 5–8, none of them significant.
The 27B’s reasoning shows a worse problem. On these bugs it often recognizes the code instead of reasoning about it: “This is exactly Heartbleed.” “I found a reference to a bug in LittleCMS 2.0.” “Usually, these prompts come from a dataset of known bugs.” All 13 FTS bugs date from 2014 to 2017, so any of the results above may be partly memory.
Buggy and fixed versions of the same function
To separate knowing from remembering, I switched to pairs. Each pair is one function in two versions, just before and just after the commit that fixed a bug. The model is asked about each version separately, with the same prompt. A model that knows where the bug is should give the buggy version the higher score, and ideally say Yes to it and No to the fixed one.
The 148 new pairs are single-function memory-safety fixes from 30 active C/C++ projects (OpenSSL, curl, QEMU, FFmpeg, SQLite, PHP, radare2, libheif, Wireshark and others), committed between 2026-05-02 and 2026-10-08. Qwen3.6-27B was released on 2026-04-21, so it cannot have seen these fixes. I kept commits whose message describes a memory-safety fix and that change one function by at most 20 lines, then dropped 8 more after reading their messages. The 100 older pairs come from PrimeVul’s paired test split, at most 6 per project, and may well be in the training data.
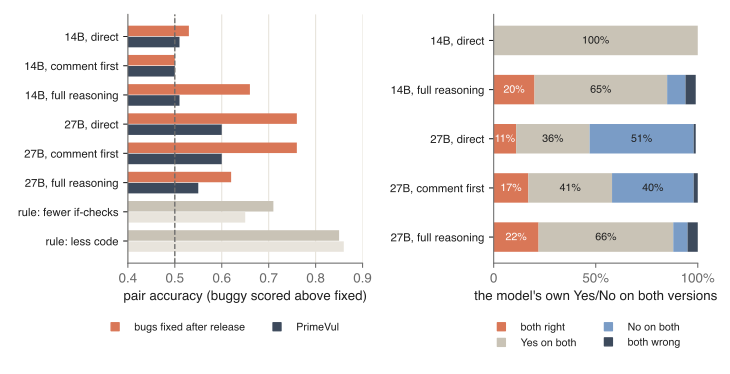
The simplest rule wins, because fixes add code. “The version with less code is the buggy one” is right 85% of the time on both sets. That only works in a paired test: when you rank the functions of a code base, there is no fixed version to compare against.
The 27B knows something beyond that rule, and on the new bugs it cannot be memory. Answering directly, it scores the buggy version higher in 76% of the new pairs. It still does in 75% of the 24 pairs where the fix adds no code, and in 73% of the 82 pairs where the fix adds no if-check, where those rules are at or below chance. It does better on the new bugs than on PrimeVul (60%), plausibly because PrimeVul’s labels are noisy and the new fixes are mostly local missing checks. The 14B shows a signal only after complete reasoning (66%).
Its Yes/No answers barely tell the two versions apart. Answering directly, the 27B gets both versions right in 11% of the pairs and says No to both in 51%. With complete reasoning it gets both right in 22%, but it also says Yes to both in 66%, and the buggy version scores higher in only 62% of the pairs. Reasoning mostly made the model more willing to call code buggy.
When it gets a pair fully right, its reasoning often names the actual bug. In the 33 new pairs where the reasoning 27B said Yes to the buggy and No to the fixed version, its explanations mostly match the fix: a double free of bs in OpenSSL’s OCSP check, the underflow of get_width() - x0 in libheif, the overflow of sz * 4 in radare2′s r_str_escape_raw, an integer overflow in expat’s xcsdup. Across all pairs, its reasoning quotes a line from the fix site for 36% of the buggy versions and 14% of the fixed ones. Counting only fixes that insert lines, so that the quoted lines exist in both versions, the gap narrows to 40% against 29%.
So what I saw in the agent transcripts holds up. A strong model can spot a bug it has never seen from the code alone, and explain it. The transcripts just don’t show how often the same model is equally sure about code that is fine.
Why this does not make a better fuzzer
Putting the results together, I don’t expect bigger models or better prompts to fix this.
- The score shifts up a little when the same function contains a bug. A fuzzer has to compare thousands of different functions, and functions differ in size, complexity and style by much more than that shift. This is why every ranking in this report loses to function size, and why the model’s Yes/No answers mean little on their own.
- Finding the function is not the bottleneck. On these bugs the oracle experiment puts the value of a perfect ranking at about 2× at most. The fuzzer reaches the buggy functions early; what remains is constructing the values that trigger the bug.
- Wrong weights can cost more than right weights gain. A bad ranking can trap the fuzzer on slow inputs or turn on expensive feedback in a hot loop, and a ranking that was merely good (the bug in the top 25%) was already slower than no weights.
Other uses of the model might still work.
- Let the model state a concrete bug, this line under this condition, and have a test or a fuzzer confirm or refute it. That is where the model is at its best. A wrong guess costs one test, and a right one points straight at the trigger.
- Use the before and after that every commit provides. Whether the paired signal can flag commits that introduce a bug is untested here, and the oracle result would still limit how much fuzzing time it saves.
- Have the model write input generators and trigger conditions. In the literature, that is where the clear wins for LLMs in fuzzing come from.
Related work
Probing hidden states for vulnerabilities
Probes for C/C++ vulnerability detection are weak and often pick up surface features. Probing the Prefill (2026) trains an MLP probe on the last-layer states of models up to 27B and reaches an F1 of 17.6 to 19.5 on PrimeVul, below the 24.5 of a fine-tuned small model; it reports no AUC and does not control for length. Activation Probes Surface Code-Security Signals (ICML 2026 workshop) reaches 61 to 67% pairwise accuracy on Python and reports that the C/C++-dominated categories are near chance. In the ablations of SAGE (ISSTA 2026), a linear probe gets about 74% balanced accuracy on PrimeVul without length control and about 50% on the time-split PreciseBugs. Code Correctness Is Linearly Decodable reports an AUC of 0.88. When I recomputed it from the authors’ released data, problem difficulty alone gave 0.82, and the probe kept about 0.65 once difficulty and length were controlled for.
Function-level vulnerability detection is near its ceiling
In PrimeVul’s (ICSE 2025) paired setting, which requires both the vulnerable and the fixed version to be classified correctly, GPT-4 scores 12.9% where random guessing scores 22.7%. Weissberg et al. (ICSE 2026) find that a classifier on 23 code metrics reaches an F1 of 20.3 against 20.7 for the best fine-tuned model, and that LLM judgments causally follow those metrics. In SAGE’s tables, frontier models reach an MCC of 0.08 to 0.14 on PrimeVul and about 0 on new data.
Context
Risse et al. (ISSTA 2025) find that 43 to 52% of real vulnerabilities depend on called functions and 40 to 47% on the arguments callers pass. Pasting raw caller and callee code makes things worse: all six settings of CPRVul degrade, and in Lira et al. (EASE 2026) GPT-4.1-mini on C drops from 75.6% to 51.0%. VulEval improves only with oracle context, the functions that the fix also touched. Selected or summarized context helps a little, as in LLMxCPG (USENIX Security 2025) and PacVD. I am not aware of earlier work combining context with hidden-state probes; here, selected context was no better than random code.
Guiding fuzzers by bug likelihood
Guiding a fuzzer by predicted bug likelihood is older than LLMs: V-Fuzz, TortoiseFuzz (NDSS 2020), SAVIOR (S&P 2020), ParmeSan (USENIX Security 2020) and AFLChurn (CCS 2021). LLM4Fuzz multiplies an LLM’s per-function score into seed energy, almost the same mechanism as llmfuzz, and its own ablation favors the complexity component over the vulnerability component. Several systems in the AIxCC final used LLMs to rank suspicious functions for their fuzzers (see the AIxCC SoK). Attention Distance (ICSE 2026) guides directed fuzzing with LineVul’s attention and is 3.43× faster than AFLGo, but has no random or code-metric control. SoK: Where to Fuzz? (AsiaCCS 2024) compares target-selection methods on 1,621 OSS-Fuzz crashes: code metrics rank best, and LineVul is close to random.
Localization is not the bottleneck
With real bug locations on Magma, no directed strategy in LibAFLGo (EuroS&P 2025) beat undirected LibAFL. AIJon (2026) places LLM-written IJON annotations at the real bug locations and triggers 34 bugs, against 38 for AFL++. Perera et al. (TSE 2023, TOSEM 2024) ran “how accurate must a defect predictor be” experiments with oracles and controlled noise for search-based testing in Java; fuzzing does not yet have a complete version of that study.
Where LLMs help fuzzing
The clear wins come from generating inputs. G2Fuzz (USENIX Security 2025) has an LLM write input generators that AFL++ then mutates, for under $0.2 of model calls per 24 hours. When the target is known, Locus (ICSE 2026) has an LLM synthesize trigger predicates as feedback and is 41.6× faster on Magma. HyLLfuzz uses an LLM in place of a constraint solver when the fuzzer stalls. All three call the model rarely. Guiding every mutation with a neural network, on the other hand, did not beat AFL++ under a fair evaluation (Revisiting Neural Program Smoothing, ESEC/FSE 2023).
If you try this
- Include a baseline that only looks at size or complexity. It beat the LLM here, and it often does in the literature.
- When you add context, add a control with random code of the same length, and compare only chunks that all received context. Context shifts the score, and comparing chunks with and without it creates effects that are not there.
- Measure what a perfect predictor is worth before building one. Here it was about 2×.
- Test on bugs fixed after the model’s release, and compare buggy and fixed versions of the same function instead of ranking a handful of famous bugs.
- With 13 bugs, medians swing wildly. Definitions as context moved the 27B’s median from 27% to 6%, with 5 bugs up and 4 down. Use paired tests.
Limitations
- The ranking and fuzzing results rest on 13 bug functions in 7 FTS targets. Fuzzing trials ran 900 s with 8 trials per configuration (1,800 s and 5 trials for libxml2 and re2), on my own engine; I did not reproduce them on AFL++.
- The engine’s seed energy ignored execution time. Adding AFL’s speed factor afterwards raised throughput 2 to 11 times on SQLite and libxml2, so a stronger engine would find these bugs sooner, and the relative order of the weightings might change.
- The oracle experiment covers 2 targets with 8 trials each.
- In the context and reasoning experiments, Qwen3-8B, 14B and 27B were used zero-shot (without a trained probe) and quantized to 4 bits; the ranking and fuzzing experiments use the trained 27B probe at full precision (fp16). The complete reasoning was generated with a different 4-bit checkpoint (AWQ) than the one used for scoring, each function’s reasoning was sampled once, and 20% of the 27B’s reasoning on the FTS subsample (30% in the paired test) hit the 8,192-token limit.
- The lenses were fit on wikitext.
- The new-bug pairs were selected from commit messages. A few of the “fixes” may only be hardening, and PrimeVul’s labels are known to be noisy.
About this report
The fuzzer, the analysis scripts and the raw results of every trial are in the llmfuzz repository (bench/ and bench/results/). The lenses are Neuronpedia’s jacobian-lens collection; the models are Qwen3 and Qwen3.6. I wrote most of the code and ran most of the experiments with Claude Code.
3. KV Cache is More Robust Than You Think in Large Language Models [kv-cache-robustness]
3. KV Cache is More Robust Than You Think in Large Language Models [kv-cache-robustness]
Introduction
Recently, I have been researching bug reproduction in SGLang and vLLM. During my bug hunting, I encountered an intriguing issue: SGLang#17839 (archive).
Two aspects of this issue caught my interest. First, the gpt-oss model (the 120b variant) only achieves 85% accuracy on the gsm8k benchmark. For readers unfamiliar with gsm8k, it is a standard evaluation dataset consisting of grade-school math problems, such as “64 cookies for 16 people, how many cookies does each person get?” It is hard to imagine a SoTA open-source model in mid-2025 struggling with a significant fraction of these questions.
Many works in our community leverage open-source models to evaluate coding ability, and during rebuttals, reviewers often ask, “What if you switch to an open-source model?” My question is: How can you trust a model that fails at grade-school math? While I am not an expert in LLM evaluation and acknowledge that methodology is often more important than the model choice itself, I strongly suggest using the best model available unless you precisely understand your model’s behavior.
The second aspect relates to the bug itself. Briefly, when using a legal but misconfigured SGLang setup, the model’s KV Cache (its context memory) becomes corrupted in the computer memory—specifically, the address pointers of the KV cache point to incorrect locations. Common sense suggests the LLM should fail to output anything meaningful, as the next token generated depends strictly on the preceding sequence. If the KV cache is scrambled, the dependency chain is broken. However, the evaluation results still showed a surprisingly high 75% accuracy. A severe infrastructure bug that scrambles the model’s entire context memory, yet barely dents the final answers.
I formed a hypothesis: humans can ignore noise in language context—for example, ignoring irrelevant conditions in “trap” exam questions. Do LLMs possess a similar ability to ignore noise within their internal KV Cache? While there is extensive research on prompt injection and KV cache compression, my investigation offers a different angle. As Anthropic noted in a postmortem of their own inference bugs, “Claude often recovers well from isolated mistakes”—standard evaluations simply failed to surface the degradation [1]. This resilience is exactly what I set out to measure.
Methodology
All results and source code are open-sourced at Nyovelt/Internal-Robustness. Most of the code was implemented by Claude Code, as the logic is straightforward. As someone who deals with the vLLM KV cache daily, I briefly examined the code to ensure the method for modifying the KV cache was technically sound.
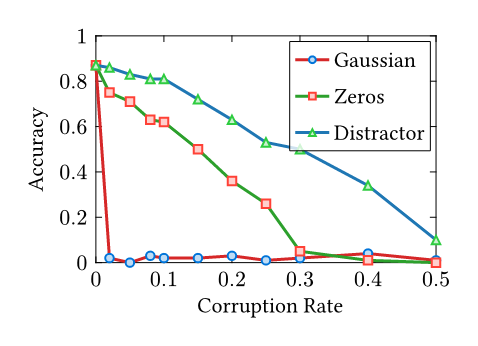
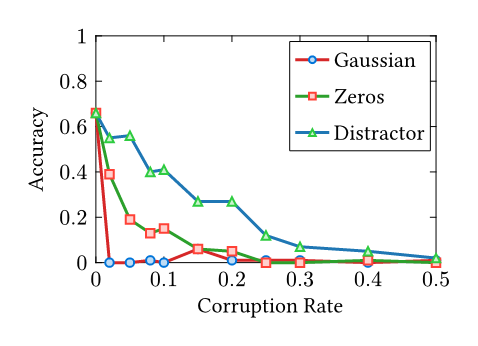
The rationale is simple: I systematically corrupt the KV cache with different noise types (Gaussian Noise, Zeros, Unrelated Prompts) and evaluate the performance on the gsm8k benchmark. I used two older but differently sized models: Qwen2.5-1.5B-Instruct and Qwen2.5-7B-Instruct.
For each corruption rate \(r \in [0, 1]\), I randomly select \(r \times 100\%\) of the KV cache entries during autoregressive decoding and replace them with the chosen noise type. Each experiment uses 100 samples from the GSM8K test split, with greedy decoding and a maximum of 512 new tokens.
For the layer-sensitivity analysis, I divide the 28-layer Qwen2.5-7B into four quarters (L0–6, L7–13, L14–20, L21–27) and two halves (L0–13, L14–27), corrupting only the selected band at three rates around the cliff point (\(r \in \{0.01, 0.02, 0.04\}\)).
The research questions are:
- How robust is the KV Cache globally?
- How robust are specific layers within the KV Cache?
Evaluation
Noise-type Comparison
| Corruption Rate | 7B Gaussian | 7B Zeros | 7B Distractor | 1.5B Gaussian | 1.5B Zeros | 1.5B Distractor |
|---|---|---|---|---|---|---|
| 0.00 (baseline) | 0.87 | 0.87 | 0.87 | 0.66 | 0.66 | 0.66 |
| 0.02 | 0.02 | 0.75 | 0.86 | 0.00 | 0.39 | 0.55 |
| 0.05 | 0.00 | 0.71 | 0.83 | 0.00 | 0.19 | 0.56 |
| 0.08 | 0.03 | 0.63 | 0.81 | 0.01 | 0.13 | 0.40 |
| 0.10 | 0.02 | 0.62 | 0.81 | 0.00 | 0.15 | 0.41 |
| 0.15 | 0.02 | 0.50 | 0.72 | 0.06 | 0.06 | 0.27 |
| 0.20 | 0.03 | 0.36 | 0.63 | 0.01 | 0.05 | 0.27 |
| 0.25 | 0.01 | 0.26 | 0.53 | 0.01 | 0.00 | 0.12 |
| 0.30 | 0.02 | 0.05 | 0.50 | 0.01 | 0.00 | 0.07 |
| 0.40 | 0.04 | 0.01 | 0.34 | 0.00 | 0.01 | 0.05 |
| 0.50 | 0.01 | 0.00 | 0.10 | 0.01 | 0.00 | 0.02 |
Results Analysis:
Random Noise Sensitivity: For unstructured random noise (Gaussian), replacing just 2% of the KV Cache results in severe accuracy degradation. Both the 7B and 1.5B models collapse at the same 2% Gaussian cliff. Likely, the attention mechanism cannot ignore values that look nothing like real data. Each corrupted step compounds into the next, and within a few tokens, the output becomes pure hallucination.
Structured Noise Robustness: For structured noise (like zeros or distractors), the model is significantly more robust. This is consistent with the behavior observed in the SGLang bug: even when replacing 30% of the KV cache with completely different content in the 7B model, it retains 50% accuracy. A possible explanation is that these “distractor” KV pairs remain within the distribution of training data—they look like real activations. The attention mechanism was trained specifically to focus on relevant context and suppress irrelevant context. It is doing exactly what it learned to do: filtering signal from noise.
Not All Layers Are Equal
To test whether certain layers are more critical than others, I divided the 28 layers of Qwen2.5-7B into four quarters and two halves, corrupting only the selected band with Gaussian noise at three rates near the cliff point.
| Layer Band | \(r = 0.01\) | \(r = 0.02\) | \(r = 0.04\) |
|---|---|---|---|
| L0–6 (early) | 0.71 | 0.64 | 0.51 |
| L7–13 | 0.79 | 0.51 | 0.20 |
| L14–20 (buffer) | 0.79 | 0.86 | 0.81 |
| L21–27 (late) | 0.43 | 0.12 | 0.01 |
| L0–13 (first half) | 0.44 | 0.10 | 0.04 |
| L14–27 (second half) | 0.34 | 0.04 | 0.01 |
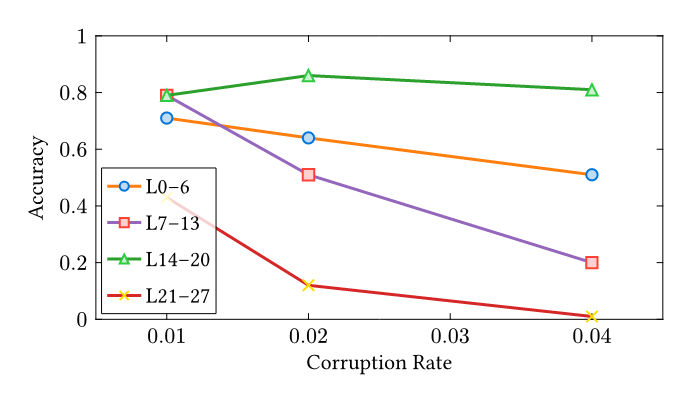
- Layers 14–20 (The Buffer Zone): These layers appear largely redundant—corrupting them barely changes accuracy (0.86 at \(r = 0.02\) vs. 0.87 baseline). They seem to perform non-critical or highly redundant functions.
- Layers 21–27 (The Reasoning Engine): These are critical. Corrupting just 2% here degrades accuracy catastrophically, from 0.87 to 0.12. These final layers appear to be where the model actually computes the answer.
- Early Layers (0–6): These are moderately robust, encoding basic language understanding with some inherent redundancy (0.64 at \(r = 0.02\)).
It resembles a factory assembly line. Disrupting the final quality-control station (late layers) ruins everything. Disrupting a middle packaging step (L14–20) barely matters because other steps compensate. Disrupting the raw material intake (early layers) causes moderate problems.
Bigger Models Are Not Tougher Against Random Noise
Both the 7B and 1.5B models collapse at the same 2% Gaussian cliff. Scale does not buy resilience against out-of-distribution corruption. However, the 7B model is more resilient against structured noise (zeros, distractors)—more parameters mean more redundancy for in-distribution filtering.
Takeaways
- Memory Fault Tolerance: Even tiny memory errors (such as bit flips) could be catastrophic if they produce out-of-distribution activations. However, if errors result in zeroed-out values instead, models are surprisingly resilient.
- Security: Activation-steering attacks that inject “realistic-looking” corruptions are harder for the model to detect than random perturbations. Ironically, however, simple random perturbations are far more damaging to performance.
- Interpretability: The late layers (21–27) are where reasoning actually happens in
Qwen2.5-7B. Layers 14–20 appear to be a “buffer zone” with high redundancy—a potential target for future pruning or efficiency research. - System Reliability: The attention mechanism’s robustness makes bugs in LLM inference systems harder to detect through output quality alone. Even a bug as severe as scrambling the KV cache might only produce a slight downgrade in the final answer quality rather than a total crash. As Anthropic’s postmortem put it, “the evaluations we ran simply didn't capture the degradation users were reporting” [1]. Attention robustness is a double-edged sword: it guarantees graceful degradation, but makes silent infrastructure failures far harder to catch.
4. Computer Science and the Big Daydream [computer-science-daydream]
4. Computer Science and the Big Daydream [computer-science-daydream]
Translated from the Chinese version by Claude. The original was written in 2020, on the blog I kept as a sophomore.
Written in 2020 Canarypwn. Was born, studying CS, will die someday.
Dreams or the Rat Race
Study-abroad application season had just ended. The school got a big harvest of offers, and it started running study-abroad workshops for the new students. Of course I went, and afterward I was even more confused. GPA, standardized English tests, connections: I had nothing to show for any of them. Still, I figured I had three years left, and with a complete strategy and plan, plus hard work, a little cleverness and a few shortcuts, it would all get sorted out in the end.
So I went to ask Vizna, and to my surprise a couple of her questions stumped me. She asked, “Why do you want to go abroad? And what are you working toward in your career?” As someone who slacks off all day on V2EX and Zhihu, I had that one ready. I answered right away: “I’m going to be the next vczh and go to Microsoft.” (vczh, 轮子哥 or “Brother Wheel” on Zhihu, is a celebrity programmer at Microsoft. The two parts of my answer don’t have much to do with each other.)
Yes. Go to places like V2EX or Zhihu, which bill themselves as a “knowledge-sharing platform” or a “community for creative workers”, and read the career threads. The first thing you notice is the criticism of how schools teach and of how work hours are run. On one hand they talk people out of biology, chemistry, environmental science, materials and electronics (no offense); on the other they fight 996. A company like Microsoft is the model employer there. Netizens wave the banner of advanced productivity and go after whatever is “backward” and “ignorant”. Here, reality beats ideals. To me, Microsoft meant high pay and lots of freedom, a place where you can make money standing up. And a master’s, besides catching me up on the latest in computing, meant bargaining power when job hunting. Everything had turned utilitarian.
But Vizna pushed back: that’s the process, not the goal. “So what are your career ideals, your life ideals?” I was lost. So I set off looking for purpose and meaning.
When I Grow Up I Want to Be…
When I grow up I’ll be a world champion, and Mom and Dad will be so happy they’ll give me my favorite Xizhilang; I’ll be an astronaut, and Grandpa and Grandma will be so happy they’ll give me my favorite Xizhilang jelly.
We had a computer at home very early. According to Mom, my dad took his first few months of pay, asked my grandparents for some more money, and bought a “Hong Yibai” (红一百) computer. By the time I can remember, though, it had broken down and wouldn’t boot.
In primary school I used Xunlei to download flash games from 7k7k, so I could secretly play on the computer whenever I was home alone. Mom was a primary school teacher, and she taught me how to make PowerPoints; for a while she was taking a computer course, and I picked up a bit of the Adobe suite along the way (though it never got her to like computers). That was when I became the class computer whiz, and computers started bringing me fun and praise.
From then on I made up my mind: when I grow up I’ll do something with computers. And it all started with 7k7k.
Then I went to middle school. Earlier, while playing CS Portable, I had made a few friends on Tieba, and Rin was one of them. She is probably one of the people who influenced me most in my life. Rin is a little older than me, knows an enormous amount about computers and loves to share it. Ever since I met her I have been following her tech stack and her footsteps.
This was when I started following everything computer-related, and probably also when I chased the dream hardest. The Steve Jobs biography we read in reading class fired up a lot of my classmates. During this time I kept hanging around Tieba, downloaded and installed all kinds of cracked software, joined a few “haxx0r groups”, and tried writing a few bits of code with C4Droid (it went nowhere). What I remember best is borrowing the library’s only copy of Easy Language from Beginner to Master (易语言, a programming language with Chinese keywords) over a school break, and reading a few pages now and then, on the break and back at school.
If the first chapter of every other programming book hadn’t gone on so much about history, maybe I’d have read more.
It was also my purest, simplest and most naive period. I kept looking for new things and trying new things. To me, computers were something sweet, like chocolate. I was like the kid in the Xizhilang ad, with unrealistic hopes for the future.
High School and the Gaokao
Thanks to a school recommendation and some luck, I got out of the high school entrance exam and into the honors class of one of the city’s key high schools. That put me on a bigger stage, and I met my high school deskmate ysc. It happened by chance: in the freshman group chat I saw a classmate say something like “isn’t VB something you should know by primary school?” and it turned out he really did, he’s way too good, so I got in touch with him. ysc is truly strong, and he was the best teacher I have met. He brought me into the school’s strongest programming club, the robotics club, and he is also the one who made me decide that I’d become a computer scientist.
In tenth grade, under ysc and the club teacher, I entered a Future Storm robotics competition and another innovation-focused robotics competition, programmed an Arduino, and won a few prizes. Later I picked up a project an older student had left behind and won first prize at the city innovation contest. Around then I also heard many stories of older students getting into Tongji through independent admission (自主招生, where a university could lower the gaokao cutoff for applicants it picked itself) by way of innovation contests. From then on, what programming meant to me changed.
In the summer after eleventh grade I entered an innovation contest that could “get you independent admission”. My goal was a national first prize, and the finished project met my expectations; to me, at least, it is one of the best things I have ever made. The next day I got the news: national third prize, a consolation prize. (It did still get me independent admission to BUPT in the end.) I wasn’t satisfied back then. I even wanted the club teacher to file an appeal. I couldn’t let it go, and all the free time I had spent on science projects seemed meaningless. The joy of making things could no longer make up for losing the medal.
In high school there was a very common pattern. Teachers had us do career planning many times and brought in lots of people, agencies included, to tell us what to do and which awards to win. They were practically telling us to get into university by any means necessary. So making things and programming became something useful to me. In the club I started asking whether a given contest was useful. ysc did the informatics olympiad, so I did it too, because in this weak province, solving the warm-up problem and brute-forcing some partial credit was enough for a prize.
Luckily, high school still had some people with ideals, like the club teacher. When recruiting he never seemed to tell us how useful joining his club would be, and he kept reminding us to find what’s fun about innovating. One club member was still entering science contests in twelfth grade. Think how much determination and love that takes.
In the end, independent admission got stricter, and the contest kids’ moods rose and fell with the policy. But for them, contests were “this is fun to learn, and it helps me get into university too”, while for me it had become “I heard this is an easy way into university”. ysc went to HUST, and I think he deserved more; another went to BIT through independent admission; and I, maybe because in high school I still made a few small things out of my dreams, also ended up at a school I’m happy with.
The Answer
Looking for purpose and meaning, I kept asking people questions. I asked about their ideals, their pasts, what they were doing.
Zhuo’er at HKU answered me like this: “The process itself is a kind of goal.” “Choosing what kind of life to live isn’t a moment where we suddenly see everything clearly and life opens up, the way we imagine. It’s a road we slowly wear into the ground ourselves, by feeling our way, succeeding and failing over and over.”
Rereading Lunyu (轮语), a collection of vczh’s sayings, I found something new:
Brother Wheel is the kind of person who, given a wheel, can play with it alone for a whole afternoon and love every minute.
How much influence does my open source project have in the community? How many people take part? Someone has already done what I’m doing, so what’s the point of me doing it? My resources are thin, my skills are outdated, my ideas are naive, my tactics flop; how could I ever pull this off? Professor He was making several hundred thousand dollars a year right after graduating, Kratos’s son got to be the God of War, Dante rides a motorcycle and becomes the Lich King without grinding problem sets…
I hesitate and overthink, maybe still with nothing to show for it, and I’m already close to 30, to 40. The original heart is gone: treating learning as pleasure, doing one thing with total focus, whatever the cost, without counting the time, ignoring the gossip…
Brother Wheel is looking for people like that.
Maybe people today are all more or less anxious and restless. So am I. My parents pinned too many hopes on me, to the point of “failure is not allowed”, and left me nowhere to retreat. The marks high school and the gaokao left on me are still there today. I think a human life is a life of alienation, and your parents’ expectations and the chase after usefulness make you run toward death faster: once all of that is done, what is left to do? What keeps people truly alive is love and hate, ideals and achieving them, and not desire and the things desire leads you to do. A life driven by desire never reaches authentic existence.
In high school I was always drawn to “free and useless” (自由而无用), and to “the use of the useless is the real use”. I had done too many useful things and too few useless ones, so I felt I couldn’t be free. Like “Go-ToDo”: every item in life is scheduled, and then you speed toward the end of the list. When every task on the list is done, what is left of life?
For computer science and my life, I want to say “stay Simple, stay naive.” As Chen Mengmeng said, keep a childlike heart like vczh’s. I no longer spend all day figuring out shortcuts to a master’s offer three years from now, which group is useful to join, how much I’ll make a year, which language is trendy, and so on. Admissions offices, evangelizing, top-end keyboards and cameras, where to eat and where to have fun, all kinds of grand narratives. These have nothing to do with my dream and are far away from me; what good does throwing myself into them do for my ideals? It only makes you look like a hysterical paranoiac. When I first learned C and microcontrollers I never thought they would help me get into No. 393 Middle Huaxia Road, and I didn’t learn C and microcontrollers to get into No. 393.
Instead, I’ll quote a cringey line from Doctor-X:
A surgeon’s skill is decided in the earliest training: by how much passion you bring to learning surgery, how many fine techniques of good surgeons you watch, and by doing the basic drills over and over, like flowing water, until you can do a perfect operation. That is the ideal surgery. And most important of all, however hard the operation, you never give up on the patient.
Computer science is the same.
I was born, I’m studying CS, I will die. I can pretty much guess I won’t do anything grand that changes the world. Living each day like a kid is probably the best description of my future.
From now on, I hope I’ll say to all the “useful” things:
Fuck off
Related
Sources
- 自招偏南-一个时代性的大梦 (in Chinese)
- 如何看待知乎大 V 轮子哥关于专业选择的言论? (in Chinese: what do you make of vczh’s comments on choosing a major?)
5. vizna’s Reply to “Computer Science and the Big Daydream” [an-reply]
5. vizna’s Reply to “Computer Science and the Big Daydream” [an-reply]
Translated from the Chinese version by Claude. The original was written in 2020, on the blog Canarypwn kept as a sophomore.
Some rambling about “Computer Science and the Big Daydream”
To Canarypwn:
“To me, Microsoft meant high pay and lots of freedom, a place where you can make money standing up”
Microsoft isn’t… Microsoft’s pay isn’t that high. Next to the big Chinese tech companies, Microsoft Suzhou is only so-so; Beijing is all right. The freedom is decent, I guess. If you want to make money lying down, that’s Google. Maybe because I’ve been at Google, honestly, I look down on Microsoft a little. But you have to know that high pay comes with productivity. If your performance is bad you won’t do well anywhere. Foreign companies can give you high pay and freedom because their employees create more value. Capital chases profit. Besides, if you don’t want to stay at the bottom and want to climb, you have to be outstanding wherever you are, and past a certain level you’ve basically given your life to work at any company, unless you’re exceptionally efficient.
In your eyes “Microsoft” is a symbol, a kind of security, but it actually isn’t anything. Getting into Microsoft won’t bring you any real achievement. It’s just an assembly worker’s contract that pays a lot more than an assembly worker gets. Capital chases profit, and the initiative isn’t yours either, especially if you hand over your survival skills without noticing. Don’t pin your hopes on one company, or a few. You should have the confidence that you could work for nobody, go solo on your own craft, and still eat, and eat well. Saying your dream is to get into company XX really just means hoping to be a high-end corporate drone. Note that I don’t mean that negatively, because I want to be a high-end corporate drone myself. But that’s because I know what I’m after, I know what I need and why I’d be a high-end drone, and not because I want to coast until retirement. The right mindset, as I see it, is “you are all my wings”. For me, Google and places like it are wings that help me pursue my ideals. If one day all these companies were gone, I’d be sorry, but there would still be countless ways to go. Your base is your own ability and your own pursuit. “How” you walk your road can change in a thousand ways, but “what” your road is shouldn’t shift with outside things. That’s a life with real direction. But you never need to rush to find a direction. I’d rather suggest “you can’t stop running, but don’t forget to think while you run”. You can start with an idea and keep revising it as you go. p.s. Go do an internship. Or research. Or open source. Experience will slowly mature your ideas.
There’s no need to reject the “useful”. They’re “useful” because they really are useful; they’re the most effective things many people found through practice. Don’t look down on them out of youthful pride. You’ll find that going your own way takes enormous nerve and drive, and luck. Most excellent people accepted the “useful” and chose some of it. Neglecting your original creativity while chasing honors? In fact the two are often not completely opposed. While chasing “direct benefits” you should not get lost in “chasing benefits”, and should learn a lot along the way. That’s the best outcome.
Also, I’ve always believed (or say it’s my Ah Q spirit, forcing myself to feel better, that’s fine too) that every choice is just a choice, not a sacrifice, and not helplessness. When you give something up on purpose, don’t feel you’ve made a sacrifice (and so deserve respect or a reward). See it as your own choice, and then don’t feel wronged by whatever comes of it. When you’re forced to accept something, don’t cling to the past too much either. Face reality and treat it as your choice too. Each choice leads down a different branch, and none is better or worse (other people’s comparisons and judgments are just them judging by their own desires). Each is a unique experience that belongs only to you, and you can gain a lot from any of them. I enjoy every stretch of experience in life. I’m after rich experiences, an understanding of the world, and an appreciation of beauty, or call it truth. I think that’s what I’ll find most precious when I look back on my life at the end.
My overall impression after reading:
This is good thinking. To me it reads a bit young and naive, but when I think back to myself at your age, I thought the same way, maybe even more naively. So I’d encourage you to keep opening up your view; it can go wider still. What ambitions do you have for this world? What do you expect of yourself? What do you want to be like, and what life do you want to live, ten, twenty, fifty years from now? Born human, and lucky enough to be born among the luckiest 1%, do you want to do something for the world? Going even further: what are your politics? Where does your faith come from? These are far off, but an independent person ought to be clear about them, meaning what values their views on everything come from, and what they are really living for. (One more thing: I think this is what a successful undergraduate education should cultivate most. It may be getting harder in the modern technological age, but undergrad should at least give people the awareness to think, though it’s something an educated person has to think about for life.)
I’ve never taken a side on which way the wind blows on V2EX and Zhihu. I haven’t hung out on Zhihu for years, though I always hear things. vczh’s reputation isn’t exactly good, and people see him in different ways. But I’d suggest you keep a little distance from V2EX and Zhihu, and don’t let the mood there seep into your thinking without your noticing. It happens without your noticing; you may even think it’s your own independent view. These days I rarely comment on current events or read all kinds of opinions, because the older I get, the more I see how thin my own thinking is. I’d suggest you not rush to absorb, join in and voice opinions, maybe not even rush to think broadly. You should think, but not churn out and publish opinions blindly while your thinking hasn’t moved. Read books, read the classics, learn the great ideas, learn how reality really is, settle down and think deeply. Staying quiet and focused will matter more and more in the future (can you focus on one thing for hours without getting distracted for even a minute?). Of course, that’s just my view. Experience and reading will make you more mature by the day. Don’t rush anything. Going by the timeline, or even ahead of it, is actually a great choice, because you won’t be too busy, and you’ll have plenty of time to savor things and explore.
p.s. You’re reading Žižek and Lacan? Smiles like a proud old mother. Try reading more books and more viewpoints. You should know the earlier ones. Try to step outside the mindset you grew up with in China; note that this means stepping up higher to look at it, not rejecting it. A few half-full bottles (oops) among the seniors in the Chinese Literature Club would be happy to throw in some random comments.
p.p.s. vizna starts with a lowercase letter, but Ingress doesn’t care about case, so it’s fine, no need to change it. Seeing this name surprised me a little.
Regards,
The Chinese Literature Club’s one true half-full bottle, who sloshes with real gusto, your old senior